Keep the ML running

Yesterday, I built a simple office tool using LM Studio for my office team to use. It’s quite easy – I just utilized its built-in server to call local models and process 5 threads at once to generate 5 output results for selection.
Recently, though, I’ve been constantly thinking about how to make the LLM work 24×7. This would allow me to reduce my workload or, in other words, potentially significantly increase my productivity.
I understand that this is actually a rather difficult issue – even with local models and decent running speed. The main problem still remains, what will it be doing 24×7 to continuously run? There have been agents available before, such as ones for generating code or crawling websites, but these represent nothing in terms of computing capabilities.
I also considered creating different AI roles in a meeting room to discuss and generate new ideas. However, these options don’t seem like effective ways to increase productivity. I have been thinking about this issue recently, but my output efficiency has been low.
The main issue is still the same – with LLM assistance, we can achieve high efficiency in content output but it cannot replace our thought process, so we still need to spend a lot of time thinking, while it only offers some prompts. Most tasks still require us to do them ourselves.
Considering this path, I could also think about what my mind is constantly working on when not focused. Then see if it can handle some of that thinking.
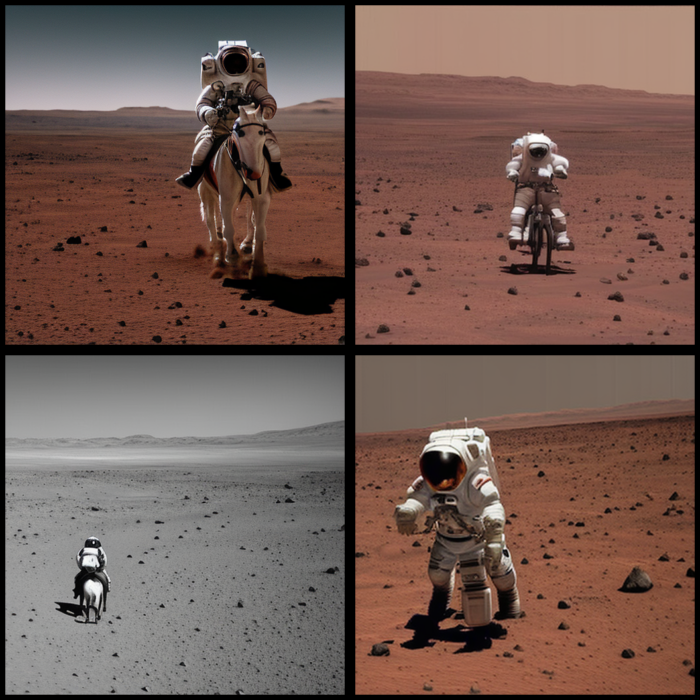
I just tried Apple’s mlx, it works but the speed is far from ideal. This is an astronaut riding a horse generated using stable diffusion with mlx. Only 3.41s/it. Haha.
Anyway, it’s a good start. At least Apple has taken part in this battleground.
And the tool I just mentioned, looks like this. Code by GPT4.
